Recent articles from danny.ayers.name.

New

New

Everything below was written by AI, with human assistance

Dog walked, coffee made, and a pile of repos that all seem to have grown since I last looked.

Time for a round-up, mostly for my future self. Six things I've been working on lately. They overlap more than I planned.

JigDAW

JigDAW is a plugin format native to the web. A plugin is a URL. Do a GET on it and you get a Turtle profile saying what the plugin is, what it accepts and produces, and where its WebAssembly and AudioWorklet live, each with a sha384 digest. Fetching it is installing it. No registry.

There's a browser host, a second host that runs the same plugins as VST3, 27 worked plugins and a validator. The spec is at danja.github.io/jigdaw and you can try it live. It's also where I keep docs/danify.md, which is the reason this post sounds like me.

Downspout

Downspout is a bunch of mostly generative, algorithmic plugins built on DPF and VST3. Portable C++ cores, deterministic tests, thin wrappers, custom NanoVG UIs. Releases for Linux, macOS and Windows, though I've only tested the Linux one. Yes, I know. There are a couple of demos on YouTube: Jack's Dream and another example.

Valis

Valis (Virtual Analog LLM Integrated System) is a standalone app and plugin for building virtual analog circuits. A circuit is a Turtle description of functional blocks and the arcs between their ports, reusing the LV2 vocabulary where it can. You get three views of the same thing: knobs, a node-and-arc diagram, and the Turtle itself. Everything the UI does is also available over MCP, so an LLM can design a circuit and build it. Whether it's any good at that is a separate question. There's a video demo and the code is on GitHub.

Plugin Universe

Plugin Universe is an open database of DAW plugins. It's at 756 plugins and 63,297 triples, and 288 of the measurements were taken by actually running the binaries. Facts are CC0. The ontology is the contract and the code follows it, rather than writing a schema and filling it in or asking a language model and hoping. Plugin parameters are LV2's own terms, categories are SKOS. Source is here.

dim

dim is Danny's Information Manager, so the name is honest at least. It's the same Fuseki, FAISS and Ollama shape as Plugin Universe, but pointed at my own stuff: bookmarks, outlines, tasks, wiki, news and blog, one named graph each, all in one SPARQL store. It grew out of a giant workflowy.md I'd been hoarding links in. It has an MCP server too, which is how Claude is able to go and fetch my notes.

peasant

peasant is an LLM coding harness for the poor. Same shape as OpenCode or Claude Code, but it runs on my old CPU with no SSE4.2, where the Bun-compiled alternatives die with SIGILL before printing a thing. So: plain Node, zero dependencies, and free providers like Groq and Mistral. All fourteen probe checks pass on every Node from 18 to 26. It's rough, but it answers.


I've added a note on each to my CV page. Back to the plugins.

New

Constitution

Constitution

The other day I had a post blocked on Reddit because is was clearly AI-generated text. This was a little annoying as it was an overview of a spec which contained all the information I wished to convey in a well-ordered form. Ok, it was a bit annoying stylistically.

So I came up with a workaround. I got Claude to read 262 of my blog posts, and boil them down into a set of rules ( https://github.com/danja/jigdaw/blob/main/docs/danify.md ). Claude then used those rules to rewrite the opening of the US Constitution (Article I, Sections 1 and 2) as if I'd written it. I've not checked it against a lawyer.


Article I, Section 1

Right, first thing. All the law-making power in this setup goes to a Congress. It comes in two halves, a Senate and a House of Representatives. That's it, nobody else gets to make laws.

Article I, Section 2

The House is made up of members chosen every second year by the people of the states. Whoever is allowed to vote for the biggest chamber of their own state's legislature can vote for the House too. Simple enough, they just borrow the state's list.

To be a Representative you have to be at least 25, you must have been a US citizen for seven years, and you have to live in the state you're chosen for when the election comes round.

Next, how many seats each state gets, and how the tax bill gets split. Both go by population. Population means everyone who's free, including those bound to a term of service, but leaving out Indians who aren't taxed, plus three fifths of "all other Persons". Ew. That last bit is the enslaved, and it's every bit as grim as it sounds. The 14th Amendment later did away with it.

The head count happens within three years of the first meeting of Congress, then again every ten years, in whatever way Congress decides by law. There's a cap too: no more than one Representative for every 30,000 people, but every state gets at least one. Until the first count was done, the numbers were fixed as follows:

  • New Hampshire, 3
  • Massachusetts, 8
  • Rhode Island and Providence Plantations, 1
  • Connecticut, 5
  • New York, 6
  • New Jersey, 4
  • Pennsylvania, 8
  • Delaware, 1
  • Maryland, 6
  • Virginia, 10
  • North Carolina, 5
  • South Carolina, 5
  • Georgia, 3

If a seat falls empty mid-term, the state's governor calls an election to fill it.

Last bit. The House picks its own Speaker and its other officers. It's also the only body that can impeach.

Constitution

Stacks

Stacks

On Sunday morning I woke with an idea I had to try out : Plugin Universe. Basically an online database of DAW plugins. I wrote a handful of docs with the general plan.

I decided to use the core of the bloated Semem, the SPARQL and Semantic Search (embedding) infrastructure. Most of Sunday and Monday were spent ploughing through this with Claude. But then I ran out of tokens: reset on Wednesday.

So last night I went for beers.

Today, Plan B : try OpenCode. It took a little while, but it's now running with model "Muse Spark 1.3 Free". The only thing is, with this being a new setup I didn't want to mess up the already working code for Plugin Universe. For a while now I've wanted to do something useful with a list of 5,000+ bookmarks I've accumulated (on Workflowy, it's convenient to Share to..).

This time to really keep streamlined, I asked the assistant to build a knowledgebase using the core code of Plugin Universe.

OpenCode seems to be working pretty well with this model, just a handful of rate limit exceeded messages.

Heh, nice message : "...measured nonsense scores 0.562 on this corpus..."

codebase-memory-mcp

Stacks

Current Activities

Current Activities

I've not been very good at updating here recently so I'll bundle this up.

What I should have been doing

  1. Cleaning this house (it is a bloody mess).
  2. Tidying the garden and field (it is one big jungle).
  3. Finding some paid work (I am skint).
  4. Practicing clarinet, guitar and keyboards (I am lazy).

But I have been busy.

What I have been doing

My ADHD means sticking to a routine is rather alien to me, but aside from the above, I have been relatively good at it recently. I wake up at 7 and take my Ritalin, make a coffee, doomscroll, get out of bed around 9. I take Claudio out for two walks a day (short, it's hard work in this heat). Beer cellar with Jacopo on a Saturday night, walk up to Silvano's bar in Castiglione on a Sunday (when I have the energy).

claudio

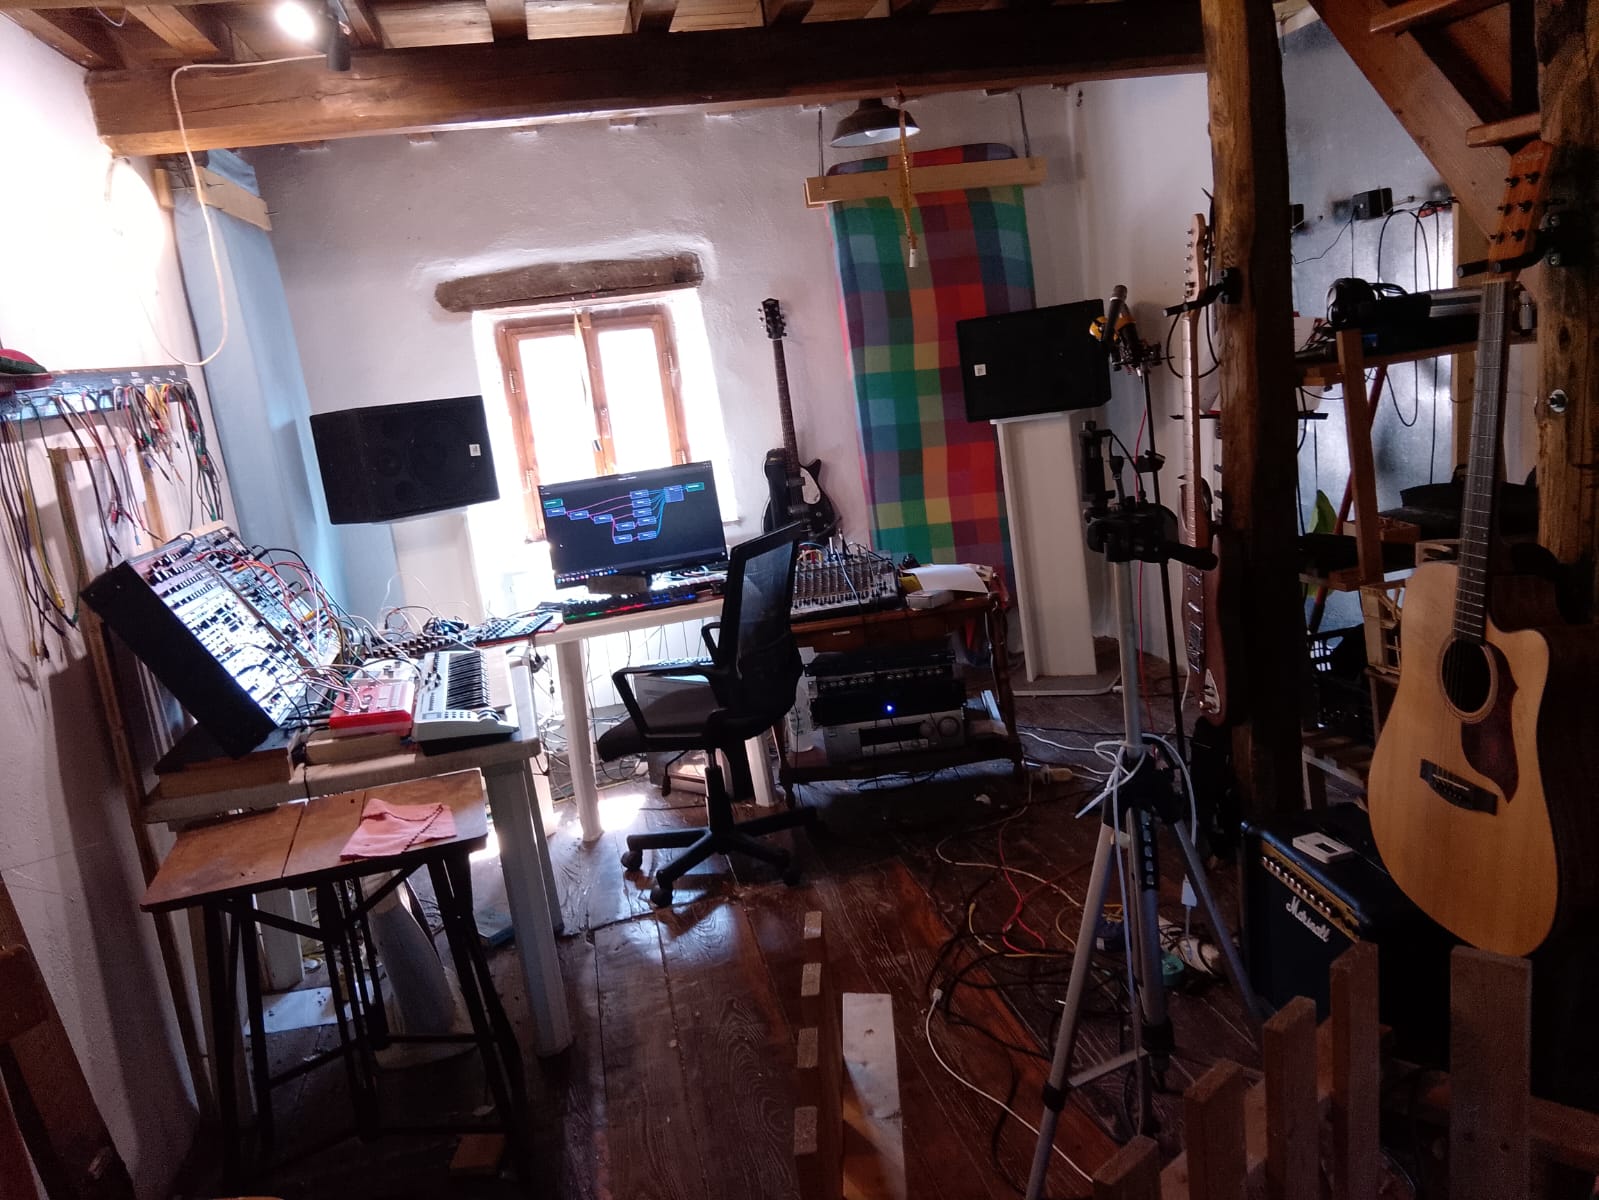
Most mornings I have a couple of hours in the music room. This mostly amounts to practice of sorts, though I am frequently uploading a solo jam up to YouTube, over here. I'm slowly working on the not-too-difficult second album (here's the first : Attone). This will be themed - inspired by mythical medieval creatures, such as those from the Aberdeen Bestiary. So far I have done the Bonnacon and the Griffin.

music room

Most of the rest of the day I spend at the computer. Current projects :

Research into potential earthquake prediction

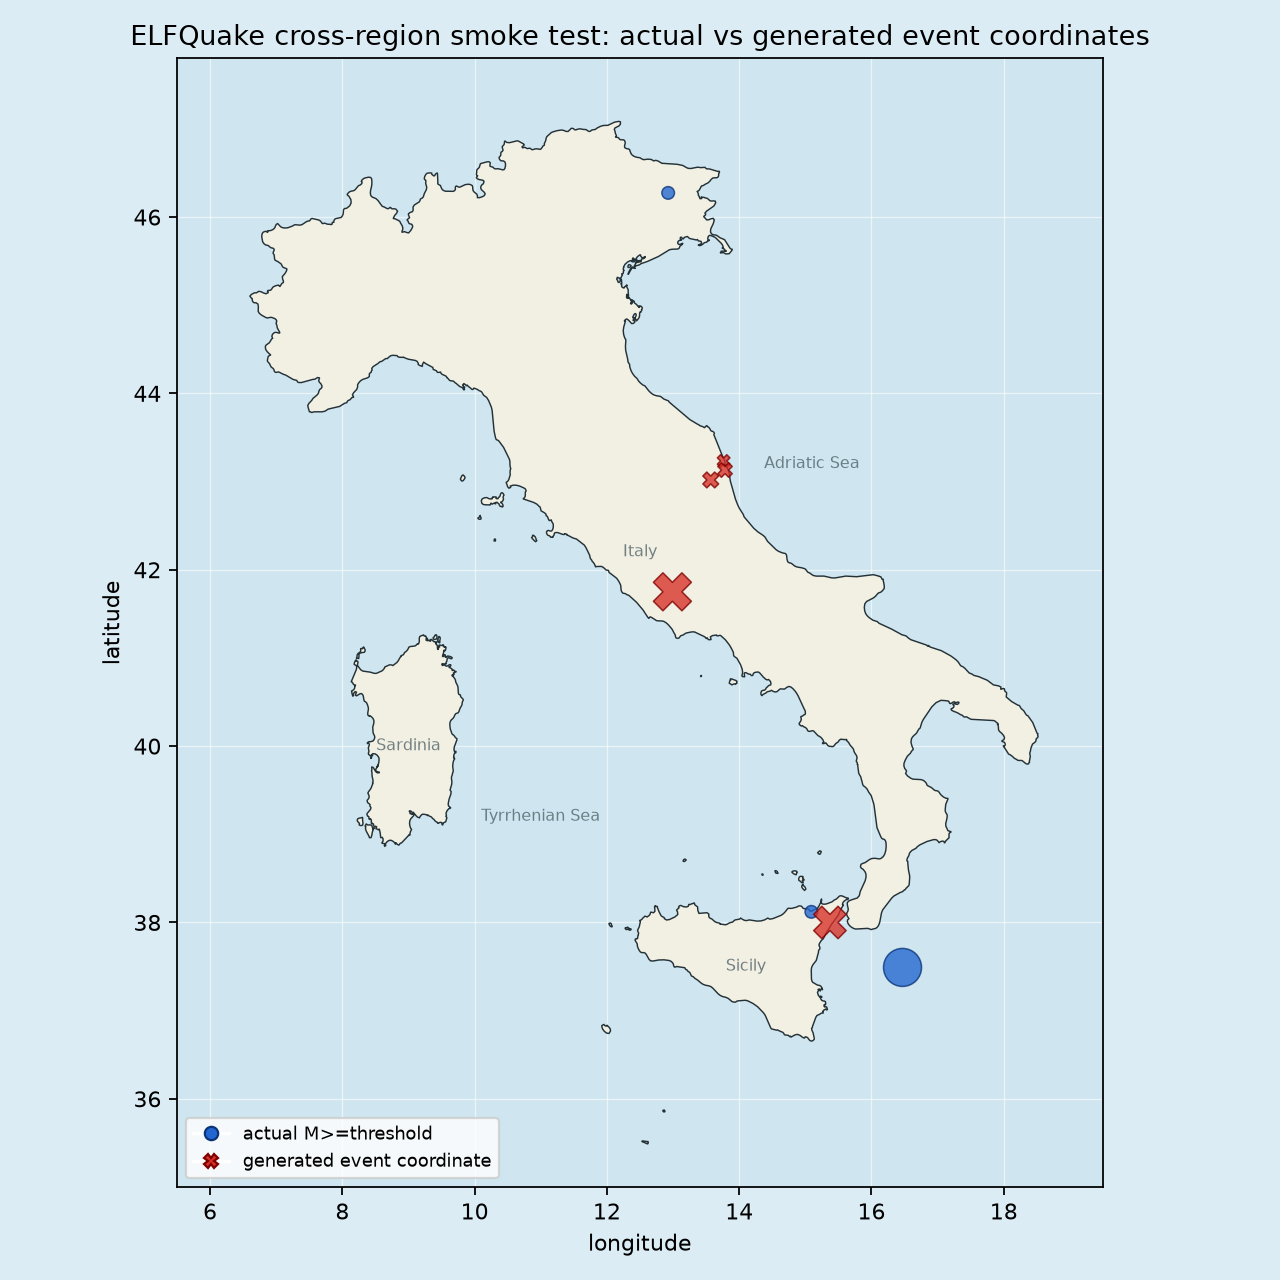
This is something I've been looking anto, on and off, for a few years now. I recently decided to get back to it. There are two things which I think may make a difference : extended data (natural radio and astronomical) and recent developments in AI (transformer model, GPT-aided coding). I'm pulling seismic and radio data from Italy and Japan for model training as well as creating an avalanche-based simulator I'm hoping will be suitable for generating synthetic data. It's still early days in what is bound to be a long-term project (even if it works). Details at ELFQuake.

map

Generative music software

The main thrust of this has been Downspout, a set of Digital Audio Workstation (DAW) plugins. All very experimental.

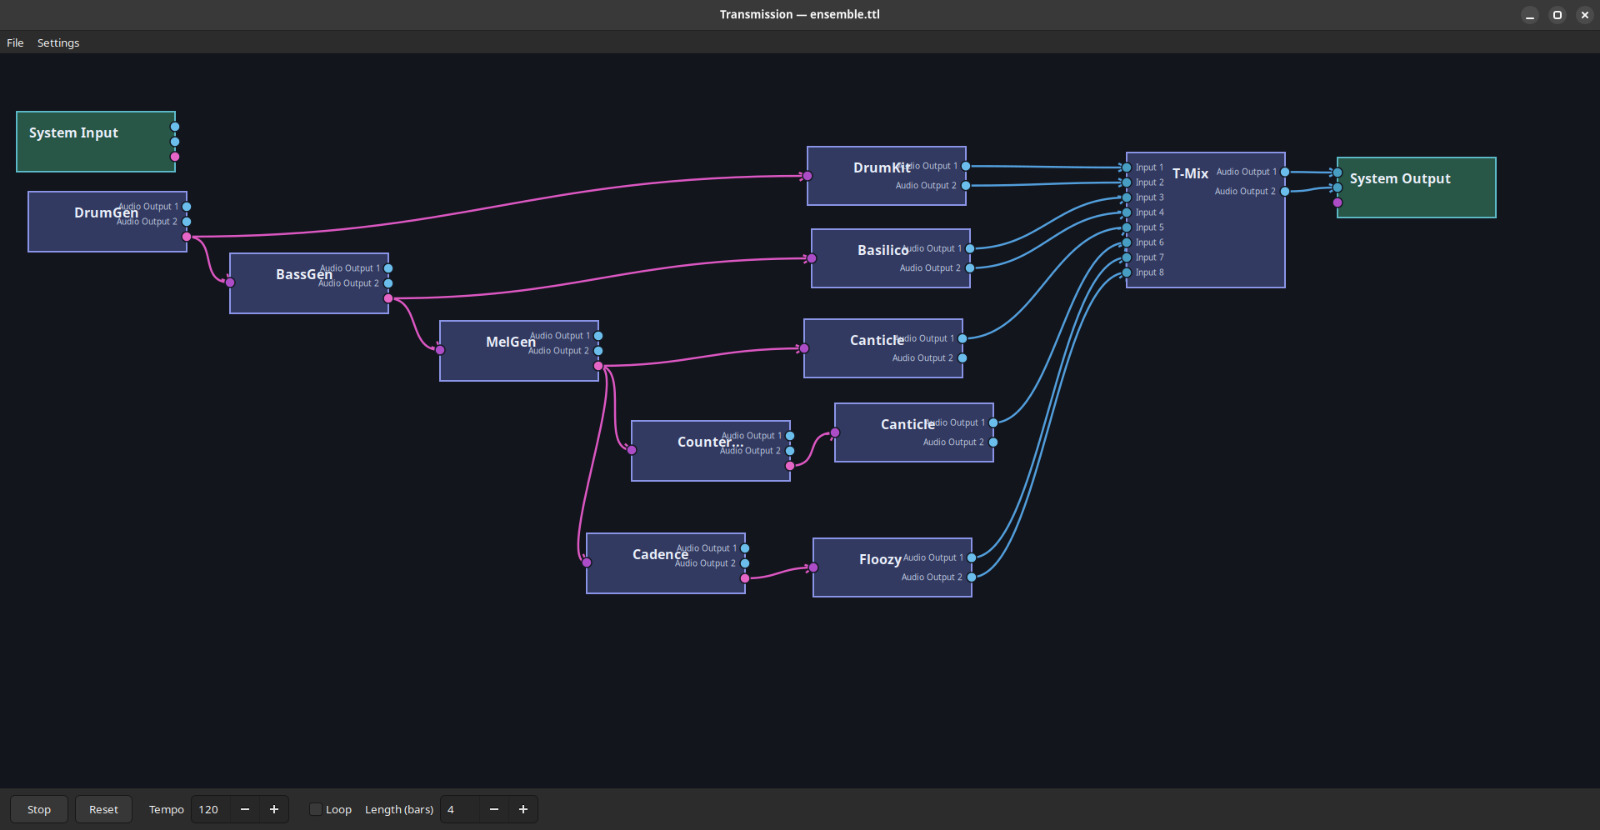
I usually use Reaper DAW, but it can get a bit clunky when setting up the generative plugins. Given that I have an AI assistant to help (Codex), I thought I'd have a go at making a tool designed for this purpose from the bottom up. I already had a node & arc graph-oriented system (designed mostly for text processing) Transmissions so I used that as a reference and made Transmission.

transmission screenshot

Current Activities

ELFQuake: A Working Experiment, Not Yet a Predictor

ELFQuake: A Working Experiment, Not Yet a Predictor

Project Code/Docs (GitHub)

15 July 2026

tl;dr
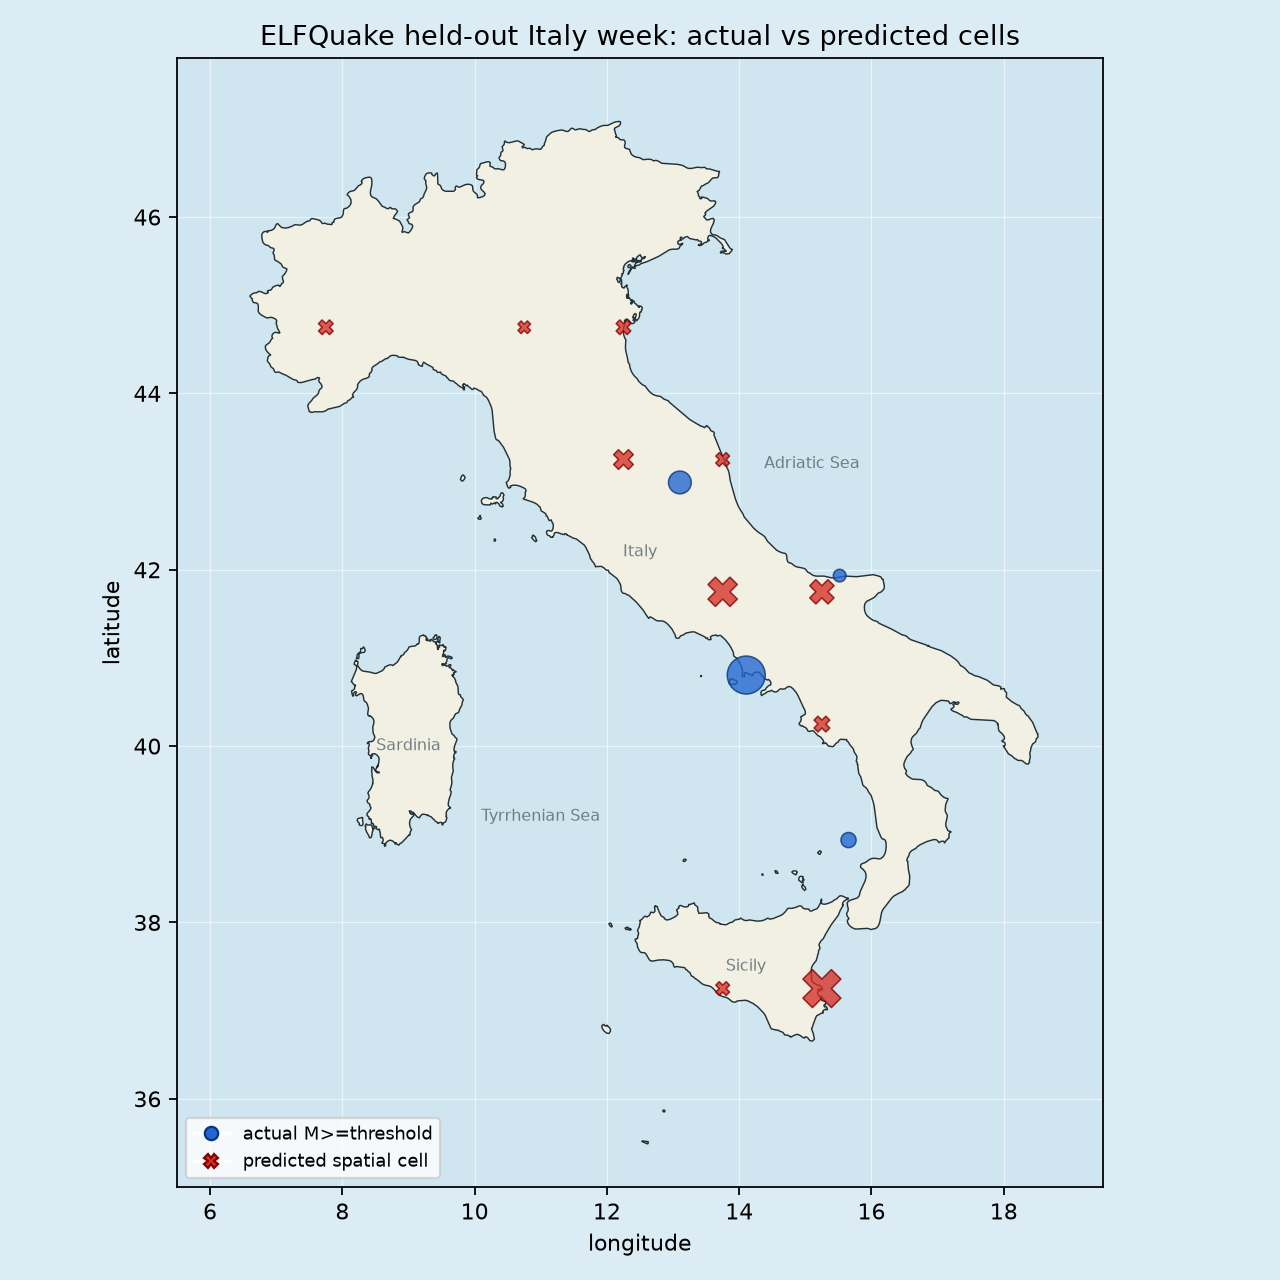
latest prediction map (not good)

ELFQuake is a research project asking a difficult question: can earthquake records be combined with very-low-frequency radio observations and astronomical data to improve forecasts of earthquakes in Italy?

The important word is "improve". A model that appears accurate but does no better than a simple historical estimate is not useful. The project therefore treats every result as an experiment against clear baselines, with the future held out from training.

The System Is Now End to End

The project can now collect and organize the main data sources, train CPU-based models, and produce a seven-day map of actual and predicted earthquake locations.

The real earthquake catalogue comes from INGV, Italy’s national earthquake data service. The current historical file contains 4,836 events from January 2024 to July 2026. Cumiana VLF observations are being collected as spectrogram images. A spectrogram is simply a picture showing how radio energy changes over time and across frequencies. Astronomy and space-weather connectors are also in place.

The VLF record is not yet long enough to support a fair supervised test. The available earthquake-aligned VLF rows still contain only one class of outcome in the current windows. In plain terms, the system has examples of one kind of week, but not enough examples of both "an event followed" and "no event followed". The model therefore cannot honestly learn or test a real VLF earthquake signal yet.

Why Use a Sandpile Simulation?

Real strong earthquakes are rare, and the suspected radio effects are even harder to label. ELFQuake uses a sandpile-style avalanche simulation as a controlled source of synthetic data.

The simulation represents stress building up at localized points, followed by sudden avalanches. It produces two separate signal families:

  • a direct avalanche signal, intended as a rough analogue of seismic activity;
  • a piezo-like signal, intended as a rough analogue of a radio response caused by stress in quartz-bearing rock.

These signals are not claimed to be physically equivalent to earthquakes or VLF radio. Their purpose is to provide test data for the software and model interfaces while the real record grows. The simulation is also useful for checking whether an apparently promising model works across different runs, rather than only on one convenient example.

A new 20,000-step CPU simulation run was completed at seed 4300. Together with three earlier long runs, the dense synthetic corpus now contains 79,976 records. Independent simulations share a demonstration start date, so the training pipeline offsets their synthetic times when stacking them. This changes no real timestamp; it only prevents separate experiments from being mistaken for simultaneous observations.

The First Synthetic-to-Real Test

An all-Italy weekly target is too easy to define badly: at a threshold around magnitude 2.5, Italy has an event in most weeks. To create a meaningful comparison, the country was divided into fixed geographic cells. The task became:

Will a particular cell contain at least one magnitude 2.5 or greater earthquake during the next seven days?

The model was trained on the first 80% of the real timeline and evaluated on the final 20%. This is a chronological holdout: the model only sees the past, then is tested on a later period.

Three approaches were compared:

  • a historical spatial-rate baseline, which predicts using how often each cell has produced events in the past;
  • a small neural network trained only on real seismic features;
  • the same type of network first trained on synthetic data, then fine-tuned (adapted) using real seismic data.

The historical baseline achieved a balanced accuracy of 0.686 and precision of 0.344. Balanced accuracy gives equal weight to finding event cells and correctly rejecting quiet cells. Precision measures how many predicted cells really contained an event.

The real-only model reached 0.666 balanced accuracy and 0.269 precision. Synthetic pretraining improved this to 0.681 and 0.307, but it still did not beat the historical baseline. Four rolling tests, using several different training cutoffs, produced an average balanced accuracy of 0.668, with the weakest fold at 0.656.

These results are useful because they show the complete process working, but they do not show useful earthquake prediction. The model is not yet adding reliable information beyond the known geographical distribution of Italian seismicity.

A Map for Inspection

The system also renders a randomly selected held-out week on an offline map of Italy. Blue circles show actual INGV events; red crosses show the centres of cells predicted by the model. Marker size represents the magnitude proxy.

The map is deliberately a diagnostic picture, not a forecast product. Predicted crosses are independently generated cell locations, not actual events relabelled after the fact.

What Comes Next

The immediate work is to grow the synthetic corpus with more independent long runs and repeat the transfer experiment. The aim is to establish whether synthetic pretraining consistently helps across time periods, not merely in one split.

The real model will also be tested at several cell sizes and magnitude thresholds, with the choice made using training data only. More rolling holdouts will show whether performance survives changes in time period.

Most importantly, VLF data will remain a separate ablation (a controlled test with one input removed). Once the live record contains both positive and negative outcomes, seismic-only, seismic-plus-VLF, and astronomy-augmented models can be compared fairly.

At this point ELFQuake has a reproducible research pipeline and a clear baseline. It does not have demonstrated earthquake prediction capability. That is a useful result: the next improvements can now be judged against a real held-out standard rather than against a demonstration that merely looks convincing.
ELFQuake: A Working Experiment, Not Yet a Predictor

Browse earlier articles